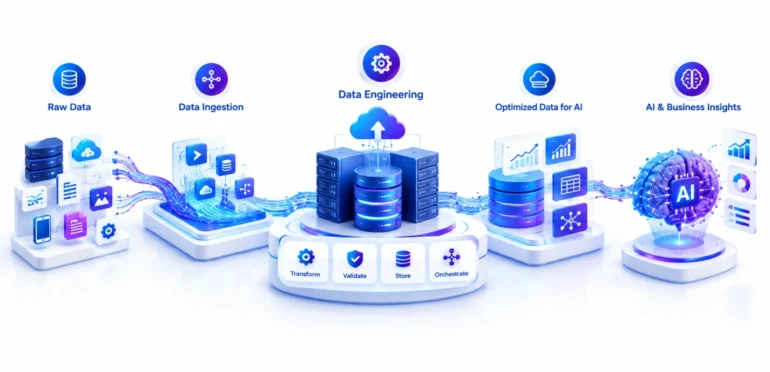
You would not build a house on sand. Yet companies try to build AI on messy data all the time, then wonder why it keeps sinking. The model is only the top floor. What holds it up is the work nobody takes photos of. This is why data engineering for AI matters more than the model everyone is excited about. Get the base wrong, and nothing above it stands for long.
And the pull toward skipping it is strong. The model is the fun part. The data work is slow and unglamorous. So teams rush to the model, build on shaky ground, and spend the next year patching cracks they could have avoided.
What data engineering for AI really involves
Strip away the jargon, and the job is to get the right data to the model, clean and on time, every time. Sounds simple. It is the hardest part of most AI projects.
Good data engineering for ai builds the pipelines that collect, clean, and deliver data without a human babysitting them. It catches bad records before they poison the model. It keeps the data fresh, so the model learns from today, not last year.
The groundwork that holds it up
- Pipelines that pull data from every source into one clean stream.
- Checks that catch bad or missing records before they reach the model.
- Fresh data on a schedule, so the model never learns from stale facts.
- A clear trail, so you can trace any prediction back to its inputs.
Why a great model cannot save bad data
People hope a smart enough model will see through messy data. It will not. Feed it junk, and it learns junk, with total confidence. That is the dangerous part. The model does not warn you. It just quietly makes bad calls that look convincing.
The oldest rule in computing still holds. Garbage in, garbage out. A model trained on dirty data is worse than no model, because people trust it and act on what it says. Clean data is not a nice-to-have. It is the whole game.
Where enterprise AI product engineering takes over
Once the foundation is solid, you can actually build. This is the next floor up, where a working model becomes a product people use every day. The move from a clever prototype to a real, reliable tool is its own discipline.
This is the job of enterprise AI product engineering. It takes a model that works in a notebook and turns it into something that scales, stays up, and fits into the way a large business actually runs. The model is the idea. This is the engineering that makes it real.
The two stack cleanly. Data engineering for AI lays the foundation, and enterprise AI product engineering builds the structure on top. Skip the first, and the second has nothing to stand on. Do the first but not the second, and a good model never becomes a product anyone can use.
How the two layers work together
Picture a company doing both right. Clean pipelines feed a model fresh, trusted data. A product team wraps that model in something users can actually work with, built to scale and watched after launch. The result holds up under real load.
Now picture the common version. A brilliant demo model, built on data nobody cleaned, never engineered into a real product. It impresses in a meeting and dies in production. Same model, opposite fate. The missing part was never the intelligence. It was the floors above and below it.
Where enterprise AI projects go wrong
Most AI failures trace back to one of these, and none of them are about the model being weak.
- Dirty data, so the model learns the wrong lessons from day one.
- No pipeline, so refreshing the data is a manual chore nobody does.
- A prototype that never got engineered into a real product.
- No plan for scale, so the thing buckles the moment real users arrive.
Each one is a foundation or structure problem, not a model problem. The right partner builds for all four from the start, because they have watched each one sink a promising project.
How to choose the right partner
The partner you pick decides whether your AI reaches production or stays a demo. A few signals tell you who understands the full stack.
- They ask about your data before they talk about the model.
- They build pipelines, not just one-off data cleanups.
- They can take a prototype all the way to a scaled product.
- They can show AI products they keep running, not just slides.
A partner who treats data and product as two halves of one job is the one worth hiring. The rest will hand you a clever model and leave the hard parts to you.
Frequently asked questions
What is data engineering for AI?
It is the work of building the pipelines that collect, clean, and deliver data to a model. Good data engineering for ai keeps that data accurate, current, and automatic, so the model always has solid input.
Why does data engineering come before the model?
Because a model learns from whatever it is fed. Dirty data produces a confident but wrong model, so the data groundwork has to come first, every time.
What is enterprise AI product engineering?
It is the discipline of turning a working model into a real product. Enterprise AI product engineering handles scale, reliability, and the fit into how a large business runs.
Do we need both for an AI product?
Almost always. Data engineering gives the model clean input, and product engineering turns it into something people can use. Skip either, and the project stalls.
How do we start without a huge program?
Begin by cleaning and automating the data for one use case. Get a model working on it, then engineer that into a small product. Prove it, then scale.
The bottom line
AI gets sold as the model, but the model is the easy part. What makes it work is the stack around it. Strong data engineering for AI lays a clean foundation, and enterprise AI product engineering builds the real, scalable product on top. Get both right, and your AI holds up in the real world. Skip either, and you are building on sand, hoping the cracks hold.